The Nut House sells roasted almonds, cashews and a walnut selection box that outsells everything else in December. It runs on Next.js with the App Router, it has about forty pages, and for two months its best category page had been sliding. Position 4, then 7, then 9, then the kind of impressions graph that makes you check whether the analytics broke.
I had three guesses about why and no way to tell which was right without opening four browser tabs and reading numbers out loud to myself. Every piece of data I needed was already sitting behind an API. What I did not have was anything holding all four in the same place at the same time.
Hermes turned out to be a decent place to hold them. There is also something pleasing about pointing a squirrel-branded audit tool at a shop that sells nuts, which I will not labour.
What Hermes actually is
Hermes Agent comes from Nous Research. It is a Python command-line agent with a full terminal interface, plus a messaging gateway so you can talk to it from Telegram while it works on a machine that is not your laptop. It keeps memory across sessions and writes skills for itself as it goes. The repository tagline is "the agent that grows with you", which is a bit much, but the practical shape is a coding agent that stays running and remembers things.
Two facts matter more than the pitch. It is MIT licensed, and it is not tied to Nous models. The provider list runs to roughly 45 entries covering OpenAI, Anthropic, Google, OpenRouter, xAI, DeepSeek, Bedrock and Azure, and it will talk to any OpenAI-compatible endpoint, which is how vLLM, Ollama, llama.cpp and LM Studio fit in. Nous Portal is the recommended route and has a free tier restricted to free models, with paid tiers from $20 a month, but nothing forces you through it.
Installation is a shell script:
curl -fsSL https://hermes-agent.nousresearch.com/install.sh | bashThen reload your shell and start it:
source ~/.zshrc
hermes
The installer puts the code in ~/.hermes/hermes-agent/, symlinks the binary at ~/.local/bin/hermes, and brings its own Python, uv, Node and ripgrep so it does not fight whatever you already have. Windows gets a PowerShell one-liner, and there is a desktop build if you want a window instead of a terminal.
Configuration lives at ~/.hermes/config.yaml, with secrets in ~/.hermes/.env beside it, pulled in with ${VAR_NAME} wherever you need them. Edit the file directly or drive it from the CLI:
hermes config              # print the resolved config
hermes config edit         # open it in $EDITOR
hermes model               # switch provider or model
If you are arriving from another agent, hermes import-agent claude-code reads your existing setup and converts it, MCP servers included. Worth knowing before you hand-write anything.
The config key that trips people up
This cost me fifteen minutes. Hermes does not use mcpServers. It uses mcp_servers, snake_case, as a top-level key in config.yaml. The camelCase JSON block you have pasted into every other agent is the shape Hermes imports from, and also the shape you use elsewhere when you run Hermes itself as a server. Inside Hermes it is YAML, and it is snake_case.
Past that, the config reference holds no surprises. A local server over stdio:
mcp_servers:
  filesystem:
    command: "npx"
    args: ["-y", "@modelcontextprotocol/server-filesystem", "/tmp"]
A remote one uses url, with headers for auth:
mcp_servers:
  company_api:
    url: "https://mcp.internal.example.com"
    headers:
      Authorization: "Bearer ${COMPANY_TOKEN}"
There is no type field on a remote entry. Streamable HTTP, as defined in the Model Context Protocol spec, is the default, and transport: sse is the only override. If the server speaks OAuth you skip headers entirely with auth: oauth, and Hermes runs the browser flow on first connect, caching the token under ~/.hermes/mcp-tokens/.
Two optional keys matter. tools.include and tools.exclude filter what a server contributes, which stops a chatty server eating your context window. If you set both, include wins. And trust: untrusted forces approval on every write-capable tool call from that server, meaning any tool the server does not annotate as read-only. The default is full, so MCP tool calls are not gated unless you ask for it. Hermes has a separate approval system for dangerous shell commands, defaulting to a smart mode that asks an auxiliary model to judge risk, but that one governs the terminal, not MCP. The practical MCP guide works through both.
After editing, restart Hermes or run /reload-mcp in a live session.
Server one: squirrelscan, for what is actually broken
This is the audit half and the part I reach for first, because a keyword tool cannot tell you that the page you want to rank has no canonical and shares its title with eleven others.
squirrelscan runs a hosted MCP server. One block:
mcp_servers:
  squirrelscan:
    url: "https://mcp.squirrelscan.com/mcp"
    auth: oauth
On a headless box where a browser flow is not going to happen, use an API key:
mcp_servers:
  squirrelscan:
    url: "https://mcp.squirrelscan.com/mcp"
    headers:
      Authorization: "Bearer ${SQUIRRELSCAN_API_KEY}"
Mint that key with squirrel keys create --shell, which offers to append the export line to your shell rc so it never lands in a file you might commit.
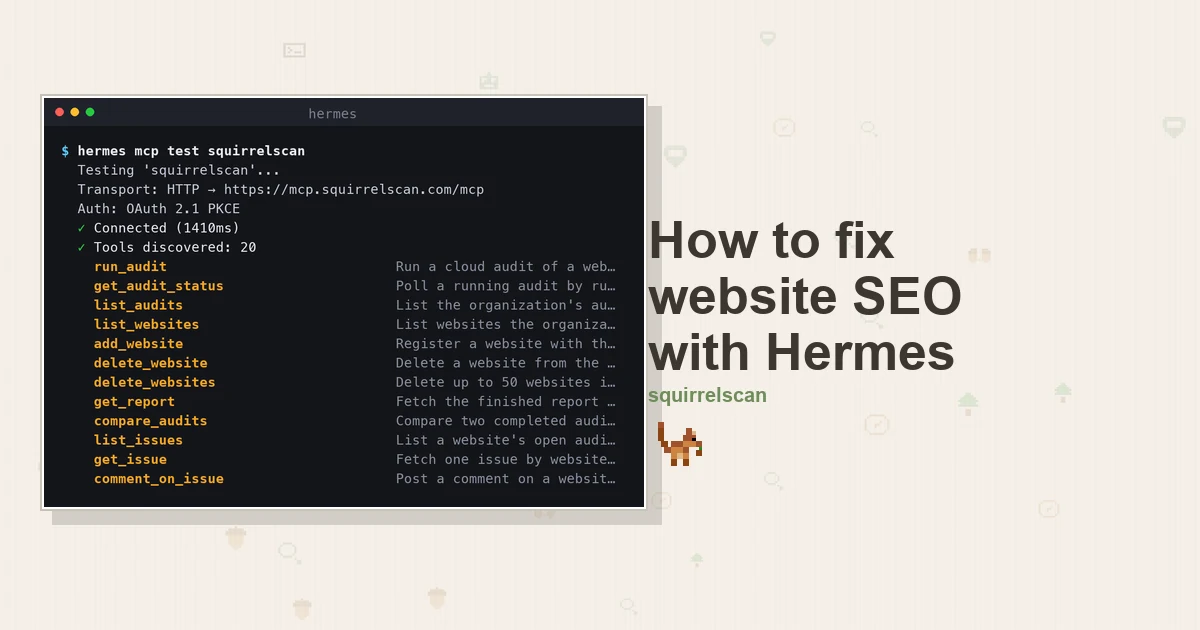
Connected, Hermes gets twenty tools. The loop is three of them: run_audit starts a crawl, get_audit_status polls it, and get_report pulls the result back as summary JSON, compact text built for a model to read, or full markdown. run_audit takes max_pages, and max_pages: 1 checks only the URL you hand it, which is the cheap way to verify a single fix. Around that core, list_issues and get_issue work a per-website tracker that persists across runs, comment_on_issue lets the agent record what it changed, and list_rules and get_rule let it look up why a check failed instead of guessing. Call whoami first, since it reports which organization the credentials belong to and what the balance looks like.
The audit runs 300+ rules across 21 categories: the familiar SEO ground, plus performance, security headers, the machine-checkable slice of accessibility, and agent experience, which is the set about whether AI crawlers can read the page at all.
You can also skip the cloud. Signed out, or with --offline, the CLI is free, needs no account, and audits from your own machine:
curl -fsSL https://install.squirrelscan.com | bash
squirrel audit https://thenuthouse.example --offline --format llm
Hermes can shell out to that whenever you would rather not spend credits. --format llm is the flag that matters, because it emits a compact structured report instead of the pretty console one.
Server two: DataForSEO, and a version trap
DataForSEO supplies the keyword numbers: volume, cost per click, competition, difficulty. It publishes an official MCP server, and it rewrote that server over the summer.
The rewrite matters because version 3 kept the npm package name. If your config says @latest, the tool surface underneath you changed from about forty typed tools to four generic ones:
mcp_servers:
  dataforseo:
    command: "npx"
    args: ["dataforseo-mcp-server"]
    env:
      DATAFORSEO_LOGIN: "${DATAFORSEO_LOGIN}"
      DATAFORSEO_PASSWORD: "${DATAFORSEO_PASSWORD}"
Those four are docs_index, docs_list_sections, docs_search and api_request. The model browses DataForSEO's own documentation, finds the endpoint it wants, then calls it through api_request. It works, and it means the server never goes stale against new endpoints, but it costs an extra round trip while the model reads the docs.
Any guide telling you to set ENABLED_MODULES is describing the old server, and that variable does nothing on version 3. The deprecated repository still carries the typed tools if you want them, where volume and cost per click came from the keywords module and difficulty came from the labs module. You would be pinning yourself to something the vendor has stopped maintaining. Worth knowing that DataForSEO's own marketing pages still show the old config with DATAFORSEO_USERNAME, which the current server accepts as an alias for DATAFORSEO_LOGIN.
There is a hosted endpoint if you would rather not run a local process:
mcp_servers:
  dataforseo:
    url: "https://mcp.dataforseo.com/v3/mcp"
This one costs money. The server is free and open source, but the data behind it is not: DataForSEO is pay as you go, new accounts get $1 in trial credit, and the minimum top-up is $50. Roughly $0.024 buys 100 related keywords, so $50 goes a long way for a shop this size, but there is no free tier to sit on.
Server three: Search Console, with no official option
Google has not shipped a Search Console MCP server. Its supported-products list covers Drive, Gmail, Calendar, Chat, Maps, People and a long tail of Cloud services. Search Console is not on it, and neither is anything wrapping the Search Console API that the community servers all call.
So this slot is community code, and you should pick it with your eyes open. I went with mcp-gsc, which is built specifically for SEO work, carries about 1,500 stars, and had a commit two days before I wrote this:
mcp_servers:
  search_console:
    command: "uvx"
    args: ["mcp-search-console"]
    env:
      GSC_CREDENTIALS_PATH: "${userHome}/.config/gsc-service-account.json"
      GSC_SKIP_OAUTH: "true"
    trust: untrusted
That ${userHome} is not a shell variable. Hermes interpolates it itself, along with ${workspaceFolder} and ${pathSeparator}, and anything else inside ${...} falls through to an environment lookup: the active profile's secret scope first, then the process environment. The server wants an absolute path to the key file, so the expansion is doing real work.
It ships around twenty tools, including get_search_analytics, compare_search_periods, inspect_url_enhanced and check_indexing_issues, which is more than you need but the useful ones are obvious.
The credential setup is the annoying part and it is the same wherever you land:
- Create or pick a project in the Google Cloud console.
- Under APIs and Services, enable the Search Console API.
- Create a service account, then create a JSON key for it and download the file.
- In Search Console, open Settings, then Users and permissions, and add the service account's email address, the one ending in
.iam.gserviceaccount.com, with Full access. - Point
GSC_CREDENTIALS_PATHat the key file.
Full access covers reading performance data and inspecting URLs. Owner is only needed for the Indexing API, and restricted access will not cover sitemap submission.
Two alternatives if that one stops being maintained. ahonn/mcp-server-gsc is the incumbent with a simpler surface, though its npm package has not moved since February. And if you want no community code in the auth path at all, Google's own bulk export pushes Search Console data into BigQuery on a daily schedule, which escapes the API's row limits and sixteen-month window, at the cost of a BigQuery bill.
The loop, on one almond page
Back to the sliding category page. The point of putting three servers in one config is that the agent can cross between them without you relaying numbers.
Audit the site. "Audit thenuthouse.example with squirrelscan and show me the worst pages." Hermes calls run_audit, shows a credit estimate if the run is expensive enough to need confirming, polls get_audit_status, and reads the report. Thirty-eight pages, health score 61. Three findings clustered on the almond section: twelve variant URLs under /nuts/roasted-almonds sharing one title, no canonical on any of them, and a category description on /nuts/almonds running to about forty words.
Pick a page worth the afternoon. This is where an audit alone misleads you. Every site has a hundred failing checks on pages nobody will visit. Ask for the failing pages, then ask which have search demand behind them.
Check the keyword. Hermes goes to DataForSEO, reads the docs for the endpoint it needs, and pulls volume, cost per click and difficulty for the phrase the page targets. "roasted almonds bulk" came back healthy enough to justify the work. The walnut selection box, whose audit rows were just as red, came back with almost nothing, so it went to the bottom of the list.
Check what Google already thinks. The Search Console server answers the question the other two cannot: is this page already ranking, and for what? /nuts/roasted-almonds was sitting around position 14 and collecting impressions for "bulk roasted almonds 1kg", a phrase that appeared nowhere in the title or the copy. That is a different fix from the one the audit proposed.
Fix it in the Next.js code. Hermes has the repository open, and in the App Router all three findings live in the same file. generateMetadata in app/nuts/[slug]/page.tsx gets alternates.canonical so the variants stop competing, and a title template that includes the weight so twelve pages stop sharing one string. The same route gets a Product JSON-LD block with price and availability. The category copy gets rewritten around the phrase Search Console said people were actually typing.
Re-audit the one page. run_audit with max_pages: 1 against the URL you just changed: 52 credits, about a minute, and a straight answer about whether the fix took. Then comment_on_issue so the tracker records what happened, which matters more than it sounds once you are doing this across a few dozen pages over a few weeks.
What each piece costs
The bill splits cleanly. Hermes is free, and so is the local squirrel CLI when it runs signed out. Search Console data is free because the API is free. squirrelscan's cloud audits are 50 credits plus 2 per audited page, against 500 free credits a month, so the thirty-eight-page audit above and a handful of single-page re-checks fit inside the free grant. DataForSEO is the only part with a floor, and $50 is the entry price.
What I would not claim is that this runs itself. The agent is good at gathering four kinds of data and bad at deciding which page deserves an afternoon. That judgment is still yours. What changes is that you make it with everything in front of you instead of reading numbers off a browser tab into a chat window.
For setup in a different agent, there is a Hermes integration page with the same config block, and equivalents for Claude Code, ChatGPT and Codex and OpenClaw. The wider SEO MCP server roundup covers what else exists and what each one is for.